Reading time: 16 minutes
The difference between SSR and CSR lies in who builds the page. With SSR, the server delivers fully rendered HTML, while with CSR the browser builds the content with JavaScript. Googlebot executes that JavaScript. The AI crawlers that Vercel and MERJ measured in 2024, however, read only the HTML of the first response.
In short
- Googlebot renders with an up-to-date Chromium, but in a step separate from crawling. In a Vercel study with MERJ, the median wait was 10 seconds.
- OpenAI, Anthropic and Perplexity don’t document whether their crawlers execute JavaScript. In the 2024 study, no AI crawler tested did.
- A September 2026 report saw OpenAI crawlers rendering pages on the author’s sites, but without official confirmation.
- So text, links, title, canonical, structured data and hreflang should be in the initial HTML. Dynamic rendering is only a workaround.
What is the difference between SSR, CSR, SSG and ISR?
The difference is when and where each mode produces the HTML. With CSR, the browser generates the content after downloading and running the JavaScript. With SSR, unlike CSR, the server generates the page on every request. In SSG, the page comes out of the build ready to serve. Finally, ISR regenerates the static version in the background, after a set time or on demand.
| Mode | Where and when the HTML is created | What arrives in the first response |
|---|---|---|
| CSR | In the browser, after the JavaScript | A shell: an empty <div> and scripts |
| SSR | On the server, on every request | Full page |
| SSG | At build time | Full page, served from a file or CDN |
| ISR | At build time, regenerated in the background | Full page, sometimes outdated |
| Streaming | On the server, in chunks | Shell and, in the same response, the finished blocks |
| Server Components | On the server or at build time | First-load HTML and RSC payload |
| Pre-rendering | At build time, running the client app | Initial state in HTML |
| Dynamic rendering | In a renderer, only for bots | Rendered HTML for the bot; CSR for people |
In Next.js ISR, the first visit after the revalidation period still gets the old version while the server builds the new one.
Are streaming and Server Components SSR or CSR?
Both deliver HTML in the first response, so they are closer to SSR than to CSR.
In streaming, according to the Next.js guide, the server first sends the shell: layout, menu and the <Suspense> fallbacks. Then each finished block arrives in the same response, inside a <div hidden> with a script that moves it into place. Because the 200 status goes out with the first chunk, a late notFound() becomes a noindex meta tag. Likewise, a redirect() becomes a browser-side redirect.
With Server Components, Next.js generates the HTML for the first load, including that of Client Components. On later navigations, only the RSC payload travels. For a crawler, however, every URL it downloads is a first load.
Does Googlebot execute JavaScript? What about Bingbot?
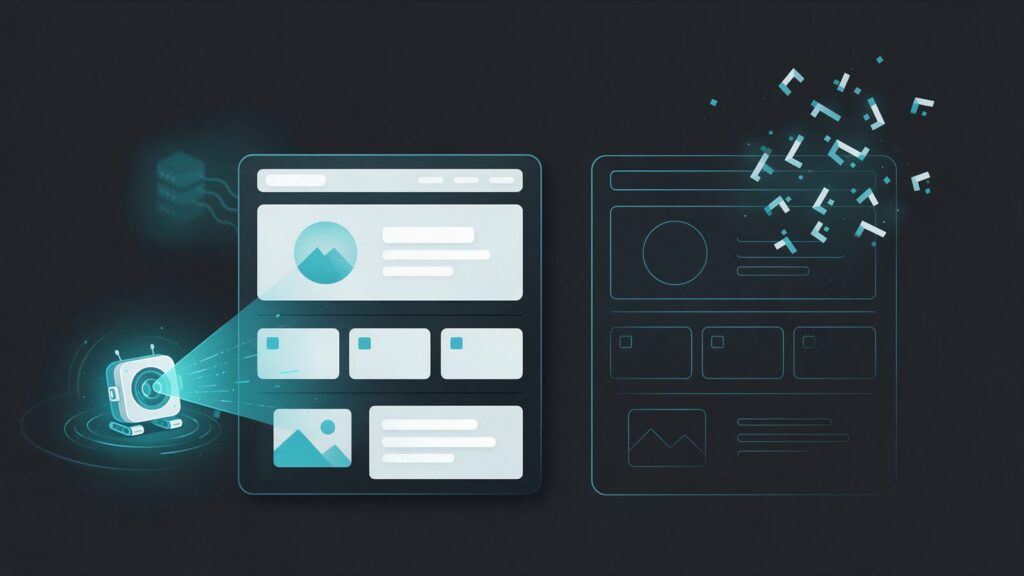
Yes. Googlebot renders pages with an always up-to-date version of Chromium, while Bingbot uses the latest stable version of Microsoft Edge. At Google, however, rendering is a separate step. The crawler doesn’t click or scroll the page, and a script error can hide content.
According to Google Search Central’s JavaScript guide, Google processes a page in three phases: crawling, rendering and indexing. It first downloads the HTML and extracts the <a href> links. Then the page enters a queue and may wait a few seconds or longer. Finally, a headless Chromium executes the JavaScript, and the rendered HTML goes into the index. So with CSR, text and links only appear after rendering, while SSR puts them in the HTML from the start.
In more than 100,000 Googlebot fetches on nextjs.org in April 2024, Vercel and MERJ saw every indexable HTML page rendered. Across more than 37,000 measured renders, the median time between crawl and render was 10 seconds. The 99th percentile, however, was about 18 hours. Note that Vercel sells hosting for Next.js, and MERJ is an SEO consultancy.
Which limits weigh on rendering at Google and Bing?
These matter most, according to Google:
- Noindex in the original HTML: Google may skip rendering, so the script that would remove the noindex may not run.
- Size: Googlebot reads only the first 2 MB of each HTML, JS or CSS file, counted uncompressed.
- No state: Google clears cookies, localStorage and sessionStorage on every load.
- No interaction: the crawler doesn’t click or scroll and declines permission requests.
AI Overviews and AI Mode use this index. So a supporting link must be in the index and eligible to appear with a snippet, as the guide to Google’s AI Mode and AI Overviews shows.
Similarly, the Bing Webmaster Guidelines, which also apply to Copilot, say not to hide critical content behind client-side rendering. After all, Bing may not index content that doesn’t render reliably, or choose it to ground generated answers.
Do AI crawlers like GPTBot, ClaudeBot and PerplexityBot execute JavaScript?
There is no official answer, because the pages about OpenAI’s, Anthropic’s and Perplexity’s crawlers don’t mention JavaScript. In addition, the most cited public measurement, by Vercel with MERJ, saw no AI crawler tested execute JavaScript. On the other hand, a September 2026 report suggests a change in OpenAI’s crawlers, still unconfirmed.
We checked the crawler pages of OpenAI, Anthropic and Perplexity, and none of them covers rendering. OpenAI’s crawler updates feed was also empty.
The Vercel and MERJ study, from December 17, 2024, used traffic from nextjs.org, the Vercel network and two job sites. These did not render JavaScript: OAI-SearchBot, ChatGPT-User, GPTBot, ClaudeBot, Meta-ExternalAgent, Bytespider and PerplexityBot. In fact, the ChatGPT and Claude crawlers downloaded scripts without executing them. In contrast, Gemini, which uses Googlebot’s infrastructure, and Applebot did render. However, Vercel, which sells hosting for Next.js, has a commercial interest in the topic.
“Brands must ensure that critical information is server-side rendered and that their sites remain well-optimized to sustain visibility in an increasingly diverse search landscape.”
Ryan Siddle, Managing Director of MERJ (2024)
The 2026 report about OpenAI
On September 30, 2026, the owner of a Japanese marketplace built on Next.js published an analysis of his own logs on DEV Community. With IPs checked against OpenAI’s lists, he saw OAI-SearchBot and GPTBot making Next.js ?_rsc= requests starting September 25. These requests only show up after the page renders. However, he found no announcement from OpenAI and thinks the change applies only to some sites. Likewise, in Internet Archive copies, the text of OpenAI’s crawler page has stayed the same since before the report.
What does this change for SSR and CSR?
So the practical rule doesn’t change: whatever a crawler needs to read must be in the initial HTML. SSR meets that rule, while CSR doesn’t.
| Crawler | Executes JavaScript? | Basis |
|---|---|---|
| Googlebot | Yes, in a rendering queue | Google documentation |
| Bingbot | Yes, with the current Edge | Microsoft documentation |
| Gemini (via Googlebot) | Yes, according to the study | Vercel and MERJ, 2024 |
| OAI-SearchBot and GPTBot | Not in 2024; report of a change in 2026 | Vercel and MERJ; unconfirmed report |
| ChatGPT-User | No, in the test | Vercel and MERJ, 2024 |
| ClaudeBot | No, in the test | Vercel and MERJ, 2024 |
| PerplexityBot | No, in the test | Vercel and MERJ, 2024 |
| Claude-SearchBot, Claude-User and Perplexity-User | Not tested in 2024 | List in the Vercel study |
Until OpenAI confirms anything, watch for the signal in your logs. To decide which crawler to allow in robots.txt, see how to show up in ChatGPT and the guide to Gemini, Perplexity and Claude. This access is the first step of GEO.
What each crawler sees in SSR, CSR and the other modes
For Googlebot, almost every mode works, with a delay in CSR and a risk when a script fails. For an AI crawler that doesn’t execute JavaScript, however, only what is already in the HTML of the first response exists. The table assumes content that comes from server data or an API.
| Mode | What Googlebot sees | AI crawler that doesn’t execute JavaScript |
|---|---|---|
| CSR | Content, after the rendering queue | Empty shell |
| SSR | Full page | Full page |
| SSG | Full page | Full page |
| ISR | Full page, possibly outdated | Full page, possibly outdated |
| Streaming | Full page | Shell and, later, blocks in <div hidden> |
| Server Components | Full page | Full page and RSC payload |
| Pre-rendering | Full page | Initial state of the app |
| Dynamic rendering | HTML from the renderer | Rendered HTML, if the crawler is on the list |
How do you see the HTML each crawler receives?
Compare the server’s first response, which is what a crawler without JavaScript reads, with the DOM after JavaScript. The DOM is close to what Googlebot renders. With each crawler’s user agent, the test also reveals the page’s rendering mode and whether it changes from crawler to crawler.
The script below downloads the same URL as each crawler and counts the text snippet, the title, the canonical, the JSON-LD and the links. The strings come from the official documentation, and W.X.Y.Z marks the browser version, as in the source. OpenAI warns that its crawler versions may change, while Anthropic publishes only the crawler names.
URL="https://www.example.com/page/"
SNIPPET="a sentence from the main text of the page"

fetch_as() {
  curl -sL --compressed -A "$2" -o "$1.html" -w "$1: HTTP %{http_code} | " "$URL"
  echo "snippet: $(grep -cF "$SNIPPET" "$1.html") | title: $(grep -ci '<title' "$1.html") | canonical: $(grep -ciE 'rel=.?canonical' "$1.html") | JSON-LD: $(grep -o 'application/ld+json' "$1.html" | wc -l) | links: $(grep -o '<a [^>]*href="[^"#][^"]*"' "$1.html" | wc -l)"
}

# Google: developers.google.com/crawling/docs/crawlers-fetchers/google-common-crawlers
fetch_as googlebot 'Mozilla/5.0 (Linux; Android 6.0.1; Nexus 5X Build/MMB29P) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/W.X.Y.Z Mobile Safari/537.36 (compatible; Googlebot/2.1; +http://www.google.com/bot.html)'

# Bing: bing.com/webmasters/help/which-crawlers-does-bing-use-8c184ec0
fetch_as bingbot 'Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko; compatible; bingbot/2.0; +http://www.bing.com/bingbot.htm) Chrome/W.X.Y.Z Safari/537.36'

# OpenAI: developers.openai.com/api/docs/bots
fetch_as oai-searchbot 'Mozilla/5.0 (Macintosh; Intel Mac OS X 10_15_7) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/131.0.0.0 Safari/537.36; compatible; OAI-SearchBot/1.4; +https://openai.com/searchbot'
fetch_as gptbot 'Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko); compatible; GPTBot/1.4; +https://openai.com/gptbot'
fetch_as chatgpt-user 'Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko); compatible; ChatGPT-User/1.0; +https://openai.com/bot'

# Perplexity: docs.perplexity.ai/docs/resources/perplexity-crawlers
fetch_as perplexitybot 'Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko; compatible; PerplexityBot/1.0; +https://perplexity.ai/perplexitybot)'
fetch_as perplexity-user 'Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko; compatible; Perplexity-User/1.0; +https://perplexity.ai/perplexity-user)'

# Anthropic: support.claude.com/en/articles/8896518 (publishes only the crawler name)
fetch_as claudebot 'ClaudeBot'
fetch_as claude-searchbot 'Claude-SearchBot'
fetch_as claude-user 'Claude-User'

# DOM after JavaScript; --virtual-time-budget gives the page up to 10 s of virtual time
# Docs: developer.chrome.com/docs/automation-and-testing/headless-cli
# On macOS and Windows, replace google-chrome with the path to your installed Chrome
google-chrome --headless --virtual-time-budget=10000 --dump-dom "$URL" > rendered.html
echo "rendered: snippet: $(grep -cF "$SNIPPET" rendered.html) | links: $(grep -o '<a [^>]*href="[^"#][^"]*"' rendered.html | wc -l)"
How do you tell whether a page uses SSR or CSR?
When the snippet and the links show up for every crawler, the page delivers fully rendered HTML: SSR, SSG, ISR or pre-rendering. If they show up only in rendered.html, it’s CSR. On the other hand, if they change from one user agent to another, there is dynamic rendering or a per-crawler rule.
Changing the user agent doesn’t turn your computer into the crawler, because the request comes from your IP. Perplexity, for example, advises allowing its crawlers in the Cloudflare WAF with a rule that requires both user agent and IP. At Cloudflare, a verified bot identifies itself by signature, IP list or reverse DNS. So curl doesn’t reproduce IP or WAF blocking, or pre-rendering served only to verified bots. A block in Cloudflare shows up in Cloudflare’s own security events and logs.
Which other tests complete the diagnosis?
- Source code versus DOM: in Chrome,
view-source:shows the server’s response, while the DevTools Elements tab shows the DOM after JavaScript. - Chrome without JavaScript: in DevTools, press Ctrl+Shift+P (Cmd+Shift+P on Mac), choose Disable JavaScript and reload. Whatever disappears then doesn’t exist for a crawler without JavaScript.
- URL Inspection: according to Search Console Help, View crawled page shows the HTML, HTTP response, JavaScript console and resources of the indexed version. However, only the live test produces a screenshot.
- Server logs: they count each crawler’s requests. But downloading .js files doesn’t prove execution. Stronger signals are API calls that the script makes and, in Next.js,
?_rsc=requests.
# Requests per crawler: log lines (Nginx or Apache combined format) with each crawler's name
for R in Googlebot bingbot OAI-SearchBot GPTBot ChatGPT-User ClaudeBot Claude-SearchBot Claude-User PerplexityBot Perplexity-User; do
  echo "$R: $(grep -c "$R" access.log)"
done

# Is the IP Google's? Reverse DNS, then forward DNS (on Windows, use nslookup instead of host)
# Docs: developers.google.com/crawling/docs/crawlers-fetchers/verify-google-requests
host 66.249.66.1
host crawl-66-249-66-1.googlebot.com

# Is the IP in the OAI-SearchBot ranges? (replace it with the IP from your log)
curl -s https://openai.com/searchbot.json | python3 -c "import sys,json,ipaddress; ip=ipaddress.ip_address(sys.argv.pop()); print(any(ip in ipaddress.ip_network(p.get('ipv4Prefix') or p.get('ipv6Prefix')) for p in json.load(sys.stdin)['prefixes']))" 203.0.113.10
The user agent can be faked, so confirm the IP: OpenAI, Perplexity and Anthropic publish lists. To audit page by page, with symptom and fix, use a JavaScript SEO checklist. After the fix, track AI traffic in GA4.
What needs to be in the initial HTML?
Everything a crawler without JavaScript should read, understand or follow. Googlebot, for instance, already collects links in the initial HTML during crawling, before rendering. The minimum list includes main text, links, title, meta description, canonical, meta robots, structured data and hreflang.
- Main text: headings, paragraphs, prices and dates, as text and not only in images.
- Links as
<a href>: Google only reliably extracts<a>links with an href that resolves to an address. So a clickable<span>and an<a>with only onclick don’t work. - Title and meta description: unique per URL, already in the
<head>of the response. - Canonical: in the HTML. Google accepts a canonical set by JavaScript, but doesn’t recommend it and asks that it not contradict the one in the original HTML.
- Meta robots: don’t publish noindex in the original HTML counting on a script to remove it.
- Structured data: JSON-LD in the server HTML. According to Google, Product markup generated by JavaScript can make Shopping crawls less frequent and less reliable.
- hreflang: in the HTML, in the HTTP header or in the sitemap; Google treats the three methods as equivalent. The last two don’t depend on JavaScript.
Common mistakes
- Content that only appears on click. Tabs and “see more” buttons that fetch the text on click hide it from crawlers. After all, Google warns that it doesn’t interact with the page.
- Lazy loading on scroll. Load when the block enters the viewport, with
loading="lazy"on images and iframes or with IntersectionObserver, not on a scroll event. - Routes without their own URL. SPAs with
#/productsor state that doesn’t change the address. Instead, Google asks for the History API, with a real URL per page. - Meta tags injected by JavaScript. Title, description and canonical created on the client only exist for those who render. In Next.js, for example, async metadata can end up in the
<body>during streaming. Only the default Next.js bot list gets the full<head>, and it doesn’t include GPTBot, OAI-SearchBot, ClaudeBot or PerplexityBot. ThehtmlLimitedBotsoption includes them, but replaces the entire list. - Soft 404 in SPAs. The nonexistent route responds 200 with an error message. In that case, Google suggests redirecting to a URL with a 404 status or adding noindex.
Are pre-rendering and dynamic rendering still worth it?
They’re worth it as a workaround, not as an architecture. After all, Google treats dynamic rendering as a temporary solution and recommends SSR, static rendering or hydration. Services like Prerender.io follow this model: they detect the crawler by user agent and serve already rendered HTML. They work as long as the crawler list and the content are right.
According to Google’s documentation, dynamic rendering “was a workaround and not a long-term solution.” It isn’t cloaking if the content is similar. However, serving completely different content to crawlers and people can be cloaking, which Google and Bing treat as manipulation.
In the prerender-node middleware, for example, the default list includes GPTBot, OAI-SearchBot, ChatGPT-User, ClaudeBot and PerplexityBot. However, it leaves out Claude-SearchBot and Claude-User, because the code looks for the string “claudebot” in the user agent. Build-time pre-rendering, by comparison, doesn’t have this risk, since it serves the same HTML to everyone.
SSR or CSR: which rendering mode should you choose to show up on Google and in AI?
Choose the mode that puts public content in the HTML of the first response at the lowest cost. For most sites, that’s SSG or ISR. SSR comes in when the content changes with every request or depends on who is asking. CSR, on the other hand, is for what doesn’t need crawlers, like logged-in areas and widgets.
- Corporate website: SSG, because the pages change little and the HTML comes straight from a CDN.
- Blog: SSG or ISR, with revalidation on each publish. WordPress already generates HTML on the server, but the risk is in plugins that build blocks with JavaScript.
- E-commerce: SSR or ISR on product and category pages, with price, stock and Product JSON-LD in the HTML. With ISR, match the revalidation period to how often prices change.
- Logged-in app: CSR behind the login doesn’t affect SEO, but home, pricing, documentation and feature pages need SSG or SSR.
How do you move from CSR to SSR in each stack?
Each stack has its own path, and on a live site everything starts with a JavaScript SEO diagnosis. SEO in React means moving away from default CSR, with SSR, pre-rendering or Next.js. For SEO in Next.js, the App Router uses Server Components by default, and the choices are between static, ISR, streaming and metadata. SSR in Angular and Vue comes from the @angular/ssr package and from Nuxt.
Lovable sites changed in 2026. According to Lovable’s documentation, apps created since May 13 use TanStack Start, with server-side rendering (on Enterprise plans, since June 22). Older ones, built with React and Vite, build the page in the browser, but on Lovable’s hosting they get pre-rendering only for verified crawlers.
When rewriting the front end doesn’t fit the deadline, pre-rendering as a service, in the Prerender.io model, buys time. Rendering is the technical foundation of the SEO that supports brand visibility in AI.
Frequently asked questions
For Google, CSR works, but with a delay and some risk. Googlebot renders JavaScript in a queue, with a median wait of 10 seconds in the Vercel study with MERJ. Also, a script error can hide content. An AI crawler that doesn’t execute JavaScript, however, gets an empty shell from CSR and a full page from SSR.
It depends on whether the text is in the initial HTML. In the 2024 Vercel study with MERJ, OAI-SearchBot and GPTBot did not execute JavaScript. A September 2026 report suggests a change in OpenAI’s crawlers, still unconfirmed. So a React site with default CSR risks reaching ChatGPT empty, and SSR avoids that risk.
Not if the content served to the crawler is similar to what people see. However, serving completely different content to crawlers and people can be cloaking, which Google and Bing treat as manipulation. Google also treats dynamic rendering as a workaround, not a long-term solution.
Main sources
- Google Search Central, Understand JavaScript SEO Basics (2026).
- Google Search Central, Dynamic Rendering as a workaround (2025).
- Vercel, The rise of the AI crawler, a study with MERJ (2024).
- Vercel, How Google handles JavaScript throughout the indexing process, a study with MERJ (2024).
- Bing Webmaster, Bing Webmaster Guidelines (2026).
- OpenAI, Overview of OpenAI Crawlers (2026).